Sports Betting Models Explained: Logistic Regression, Machine Learning, and Neural Networks
Learn how sports betting models use logistic regression, tree-based machine learning, and neural networks to estimate outcomes and validate predictions.
Sports Betting Models Explained: Logistic Regression, Machine Learning, and Neural Networks
Sports betting models can range from a short mathematical equation to complex machine learning systems. A model might estimate whether a team wins, how many points will be scored, or how often a player's statistical total exceeds a line. Logistic regression offers an interpretable baseline; tree-based methods capture nonlinear relationships; neural networks offer greater flexibility but also bring new validation demands. This guide compares these sports prediction algorithms and explains what makes a machine learning betting model credible: properly time-stamped data, honest out-of-sample testing, probability calibration, and ongoing monitoring. The most sophisticated model is not automatically the most useful for evaluating sportsbook prices.
How Sports Prediction Algorithms Are Built
The Target and Available Features
The prediction target determines the algorithm and evaluation method. A binary win-loss market calls for a probability; scoring margin requires a numeric distribution; a player total needs an estimate of the full range of outcomes. Features should represent information available before the forecast: team efficiency, player usage, opponent quality, rest and market context.
Data Preparation and Time-Based Validation
Reliable preparation includes missing-value handling, stable identifiers, opponent adjustments and cautious feature engineering. Training and testing should be ordered chronologically. If the same game or a later news report informs both training and test records, measured performance may be too optimistic.
Why Calibration Matters
Calibration means that predictions near 70% materialize in approximately 70% of representative cases over a sufficiently large sample. A model may rank stronger teams correctly while assigning overconfident percentages. For comparing sportsbook prices, the quality of probabilities is often more useful than simple ranking ability.
Three Major Modeling Approaches
Logistic Regression
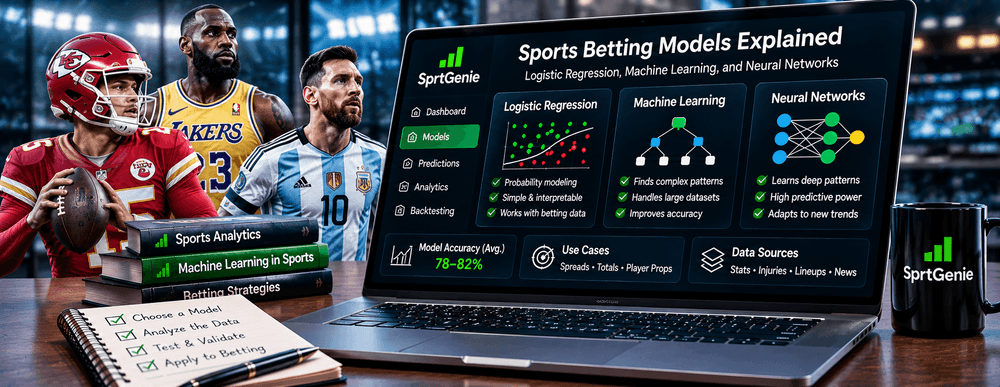
Logistic regression models the probability of a binary result through a weighted combination of features passed through a logistic function. It is interpretable, comparatively easy to audit, and a strong baseline for moneyline research. It may miss nonlinear relationships unless interaction features are supplied.
Tree-Based Machine Learning
Tree-based techniques such as random forests and gradient-boosted trees capture threshold effects and interactions without manually specifying every relationship. A machine learning betting model using these methods can incorporate heterogeneous features, but complex hyperparameter tuning can overfit historical seasons.
Neural Networks
Neural networks can approximate rich relationships among players, opponents, context and sequences. Their flexibility becomes useful when data volume and architecture fit the problem, but they require careful regularization and monitoring. A network with more parameters is not automatically more accurate or better calibrated than a simpler model.
Ensembles and Hybrid Models
Ensembles average or combine model predictions to reduce dependence on one approach. Market-implied probabilities can be informative inputs, but the training setup must establish what prices were available at forecast time. A hybrid model should prove out-of-sample benefit compared with a straightforward market baseline.
Worked Example and Reference Tables
| Method | Strength | Main limitation |
|---|---|---|
| Logistic regression | Simple and interpretable | Limited nonlinear patterns |
| Boosted trees | Feature interactions | Overfit / tuning risk |
| Neural network | Flexible complex patterns | Data needs / opacity |
| Ensemble | Combines signals | Integration complexity |
| Evaluation method | What it measures | Direction |
|---|---|---|
| Accuracy | Correct class share | Higher, with context |
| Brier score | Squared probability error | Lower is better |
| Log loss | Surprise of observed results | Lower is better |
| Calibration | Probability vs frequency | Closer agreement |
Evaluating Model Quality Correctly
Accuracy Versus Log Loss and Brier Score
Accuracy counts correctly classified outcomes at a chosen threshold. Brier score averages squared differences between probabilities and binary outcomes; log loss punishes confident wrong forecasts heavily. Each answers a different question. A model scoring 65% on favorites may still be less informative than calibrated probabilities close to market prices.
Backtesting Without Look-Ahead Bias
Walk-forward testing simulates deployment: fit models on past games, predict the next period, record results, then update training without peeking ahead. Changing league rules, roster structures or sportsbook conditions can erode performance, even after an impressive historical backtest.
Calibration Curves and Segment Performance
Calibration curves group predicted percentages and compare them with observed frequencies. A group of 60% forecasts should win around 60% in a large representative sample. Separate checks by sport and market can reveal weak segments hidden in an aggregate score.
Operational Robustness and Model Drift
Operational robustness involves missing data, feed delays, model versioning and changing relationships over time. A beautifully calibrated historical model can become stale if injury feeds fail or lineup conventions change. Model monitoring should track both statistical outcomes and data pipeline reliability.
How to Interpret SprtGenie AI Analysis
From Prediction to Market Comparison
A SprtGenie prediction should be understood as a probability estimate to compare with the price of an equivalent market. Market-derived implied probabilities are not the same as model forecasts. Evaluate the same event, selection, threshold and timestamp before interpreting a difference as a possible edge.
Look for Transparency, Not Buzzwords
Credible platforms explain testing periods, populations of forecasts, sample sizes and publicly graded outcomes. Do not assume that marketing references to AI or deep learning prove strong performance. Ask whether results are reproducible and whether the model beat simpler baselines in genuinely unseen data.
Practical Model-Selection Checklist
Choose models for the target and data available. Prefer transparent baselines, chronological evaluation, calibration monitoring, documented preprocessing and stable operational updates. Complexity is worthwhile only when it improves validated performance enough to justify additional maintenance and interpretability costs.
A credible model earns trust through evaluation against future data, calibrated output and transparent results, not through an impressive algorithm label.
Practical Case Study
Suppose a binary classification model outputs 70% on 100 events and only 40 occur. The observed 40% frequency is far below its stated 70% expectation; that would be a serious calibration concern, though formal uncertainty depends on sampling and independence. A simpler logistic regression baseline giving 45% for the same events may be closer to the frequency despite ranking some games less effectively. The comparison illustrates why 'accuracy' and probability quality are not synonyms.
A good experiment would train both systems on earlier seasons, reserve a later period without re-tuning, and compare Brier score, log loss and calibration. The more complex model could still win if it improves those metrics consistently; the point is to demand evidence. Data pipelines also require versioning: injury tags, player IDs and pregame prices should be frozen at the issue time. When missing feeds or later market changes are concealed, an impressive backtest can become misleading. Model transparency is therefore an engineering and editorial requirement, not just a matter of explaining an algorithm's name.
FAQ:
1. What are sports betting models?
Sports betting models estimate probabilities or statistical outcomes from historical and current information. Their targets may include game winners, scoring margins, totals or player statistics. They are useful only when inputs, validation procedures and limitations are clearly defined.
2. What is a machine learning betting model?
A machine learning betting model learns relationships between observed features and historical results. Examples include tree-based methods and neural networks. Complexity alone does not establish predictive accuracy; results must be tested on later games that were not used for model fitting.
3. How does logistic regression predict winners?
Logistic regression combines weighted features and transforms the result into a probability between zero and one. It is widely used as a transparent baseline for binary outcomes. Nonlinear patterns may require interactions or a different modeling approach.
4. What are sports prediction algorithms?
Sports prediction algorithms are mathematical procedures that transform data into projections or probabilities. They range from simple rating systems to simulations and complex machine learning models. A useful algorithm should match the prediction target and data available when forecasts are issued.
5. Are neural networks always more accurate?
No. Neural networks can fit complex patterns, but that flexibility can encourage overfitting when data are limited. Simpler logistic or tree-based models may match or outperform them on unseen sports events. Validation matters more than the sophistication of the name.
6. What is model overfitting?
Overfitting occurs when a model learns noise and idiosyncrasies in its training dataset rather than durable relationships. It may perform impressively in backtests but poorly on later events. Chronological holdouts, restrained tuning and regularization help reveal this risk.
7. Why are time-based test sets important?
Time-based test sets approximate how predictions are used in practice: train on the past, predict the future. Random mixing may let information from later seasons influence earlier examples and exaggerate performance. A final untouched period is particularly valuable.
8. What is a Brier score?
Brier score is the average squared difference between a predicted probability and the observed binary result. Smaller scores are better. A forecast of 80% that loses receives a large penalty, making the metric informative for probability quality rather than simple winner selection.
9. What is probability calibration?
Calibration describes whether predicted probabilities match observed frequencies. If numerous events predicted near 60% succeed approximately 60% of the time, that range is reasonably calibrated. Calibration needs sufficiently large and representative samples, with uncertainty reported.
10. Can model performance change across seasons?
Yes. Roster turnover, rule changes, data pipeline problems and shifting market behavior can weaken a previously effective model. Performance should be tracked by season, sport and market, with periodic retraining and validation rather than assuming historical success will persist.
SprtGenie provides research and analytics, not a sportsbook or a guarantee of outcomes. Sports betting involves financial risk. 18+; follow applicable laws and responsible-gambling safeguards.